
CloudTalk Call Analytics, Automated: Gemini Scores Every Call via the API
The Shopify brand I help operate runs its phones on CloudTalk. Every call gets recorded, which is great in theory, except none of those recordings were doing anything for us. They were just sitting there. Hundreds of calls a week: order issues, address corrections, mobile payment confirmations, post-delivery feedback calls. The only way to know what happened on any of them was to actually go listen to one.
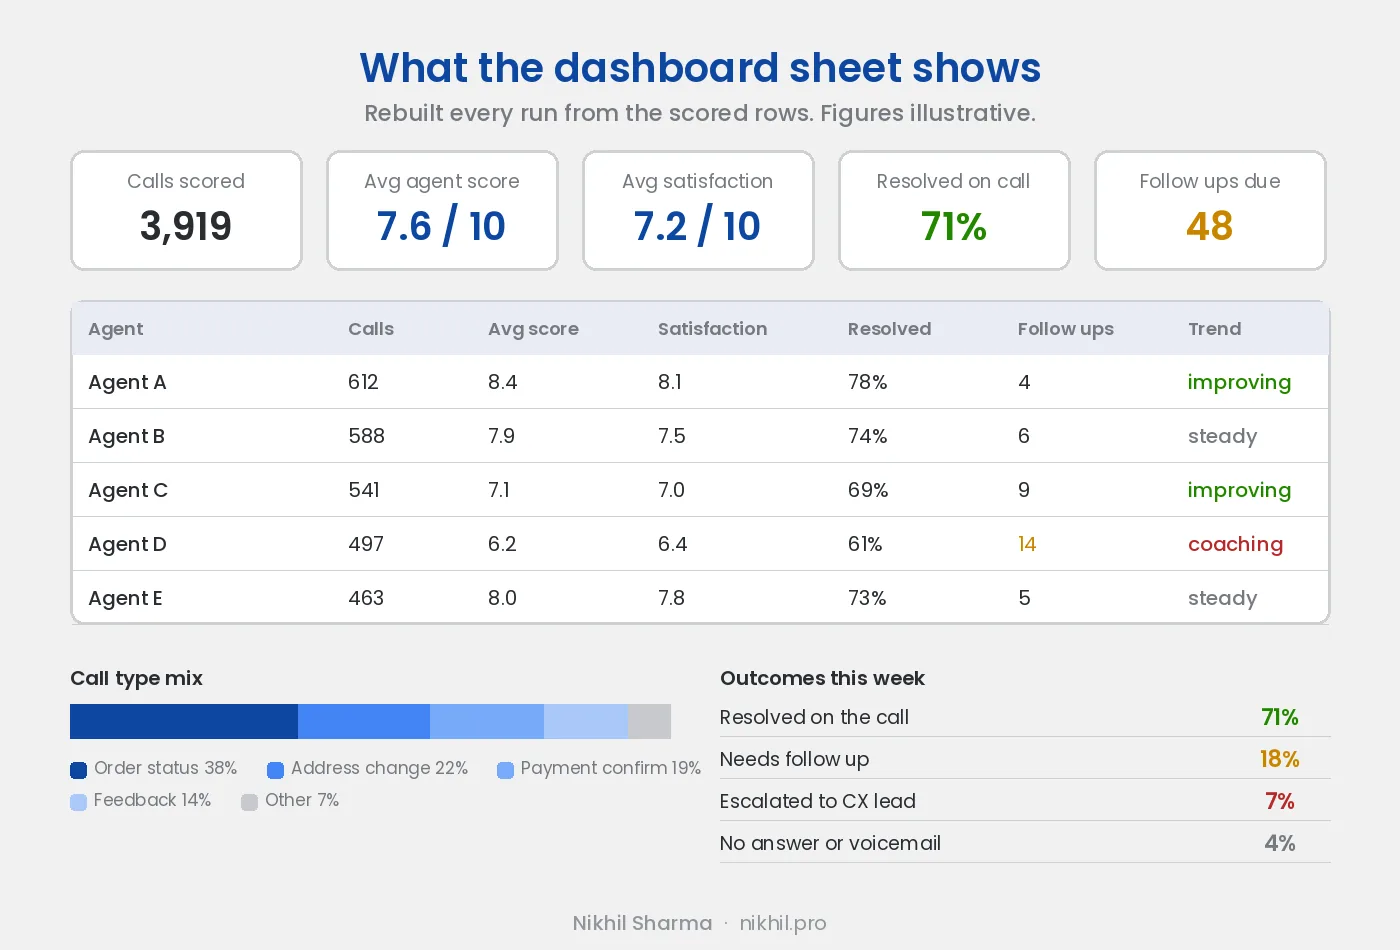
I wanted that data alive. Per-call, structured, sortable. So I built a pipeline that pulls each recording, runs it through Gemini Flash (2.5 when I built it, 3.5 now, more on that below) with a heavily customized brand prompt, and drops the result into a Google Sheet my non-technical team actually uses. That’s the whole story. Here’s how it came together.
What CloudTalk’s own call analytics gives you, and where it stops
CloudTalk’s built in analytics are about the shape of the calls: volume by hour and agent, answered against missed, wait time, talk time, outcomes if the agent tags them. That is useful for staffing and it is where most teams stop. What it cannot tell you is what was said. Whether the agent confirmed the address, whether the customer hung up annoyed, whether a refund was promised, which order the call was about. All of that sits inside the recording, and the recording is the one thing the dashboard does not read.
This post is about adding that layer: the same recordings, scored and summarised by a model, next to the numbers CloudTalk already gives you.
The Real Problem
The brand has a specific shape: a perishable product, time-sensitive shipping, a few payment and delivery quirks that generate calls, and a customer base that is bilingual.
The phone system handled the calls fine. Shopify handled the orders fine. The helpdesk handled the tickets fine. None of them talked to each other in any useful way, and the recordings, the most information-dense thing in the entire stack, were untouched.
- The CX team would open a helpdesk ticket with no idea the customer had also called twice.
- Asking the ops lead how an agent was doing got a feeling, not a number.
- Monday reporting took two hours and nobody trusted it.
What I needed was a thin layer that would pull the recording, run it through an LLM that actually understood our business, and write the result somewhere my team could see and act on.
Why I Did Not Build a Web App
My instinct was to build a real internal tool: a web app, a database, a deploy pipeline. I’ve shipped that plenty of times and I know how to make it nice. I talked myself out of it within a day :)
A spreadsheet is in production the moment you share the link. No CI, no auth provider, no DNS, no on-call. When the ops lead asks for a new column or wants follow-ups colored red, that’s a ninety-second change instead of a ticket and a deploy.
My team already lives in Sheets. They sort, filter, and pivot in there every day. Asking three non-technical people to learn a new internal tool, even a beautiful one, would have introduced the kind of friction that kills adoption.
Will this scale to ten times the volume? No. But by the time we hit ten times the volume, I’ll know exactly what to build, because the Sheet will have spent a year telling me. ^_^
The Pipeline
The whole thing is a script attached to a Google Sheet, a few hundred lines, running on a schedule. Same flow every time:
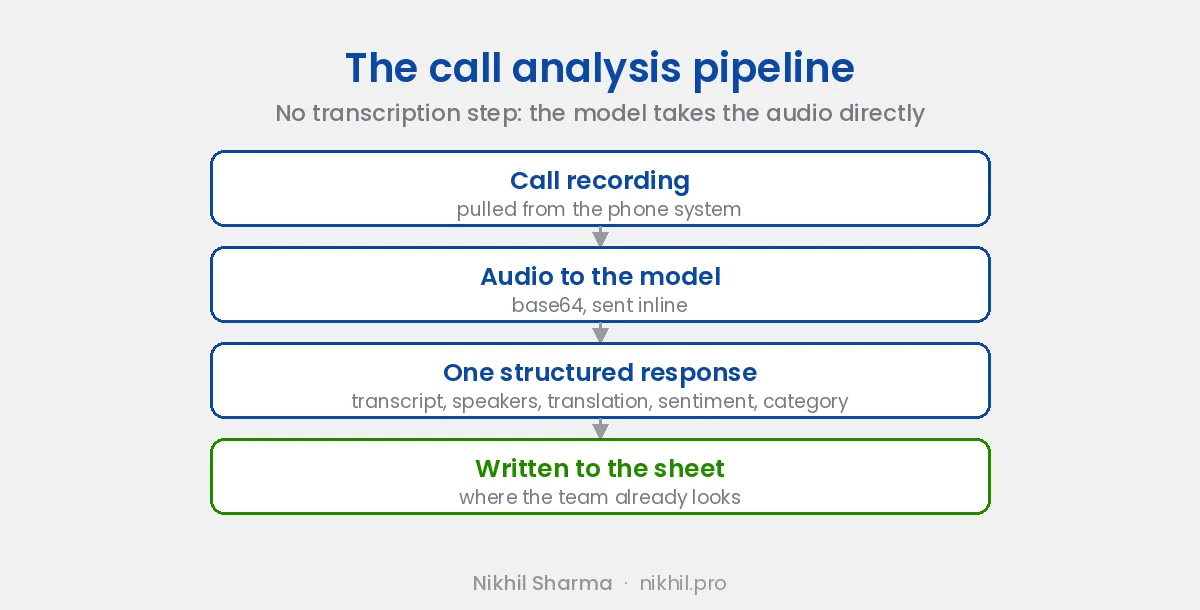
- Pull new recordings from the phone system.
- Find the caller’s most recent Shopify order for context.
- Send the audio and the order context to Gemini Flash.
- Write the structured result as one row in the sheet.
- Leave a short summary on the customer’s helpdesk ticket.
The last step had a side effect I did not plan: tickets that used to float free of any customer record now sit on the right person, with their order history next to them.
A second sheet, the dashboard, gets rebuilt every time new calls come in. KPI tiles at the top, an agent leaderboard in the middle, three pie charts at the bottom. The ops lead opens it in the morning, sees who needs follow-up, sees if anyone’s score dropped overnight, and acts on it before standup.
The Prompt Is the Product
The Gemini call is technically the simplest part of the system. The prompt is the part that took the most work and matters the most.
It’s roughly fifteen hundred words and reads like an onboarding doc for a new QA analyst:
- The business: what we sell, where we ship, how ordering and delivery work, and the kinds of calls agents make.
- The tone standard the team is coached to.
- What good looks like on each kind of call, and what bad looks like: long holds, monotone delivery, abrupt endings, vague callback promises.
- A strict taxonomy of call types and order issue types. Let the model pick its own labels and every row is inconsistent and the dashboard is useless.
Then it asks for a single JSON object: call type, sentiment, agent score, satisfaction score, outcome, follow-up flag, summary, key topics, flags, and two transcripts (original language with speaker turns, and an English translation). The dual transcript made the sheet usable for stakeholders who don’t speak Spanish.
The Model: Why Flash, and What Happened When 2.5 Was Retired
I built this on Gemini 2.5 Flash for one reason that outweighed everything else: it takes the audio file directly. No transcription service in front of it, no Whisper stage, no second API bill, no pipeline step that can fail on its own. The recording goes in with the order context and the prompt, and one structured JSON comes back with the transcript, the speakers, the translation, the scores and the category.
For a Spanish and English support line that mattered twice over, because the model hears the tone it is scoring instead of reading a transcript that lost it.
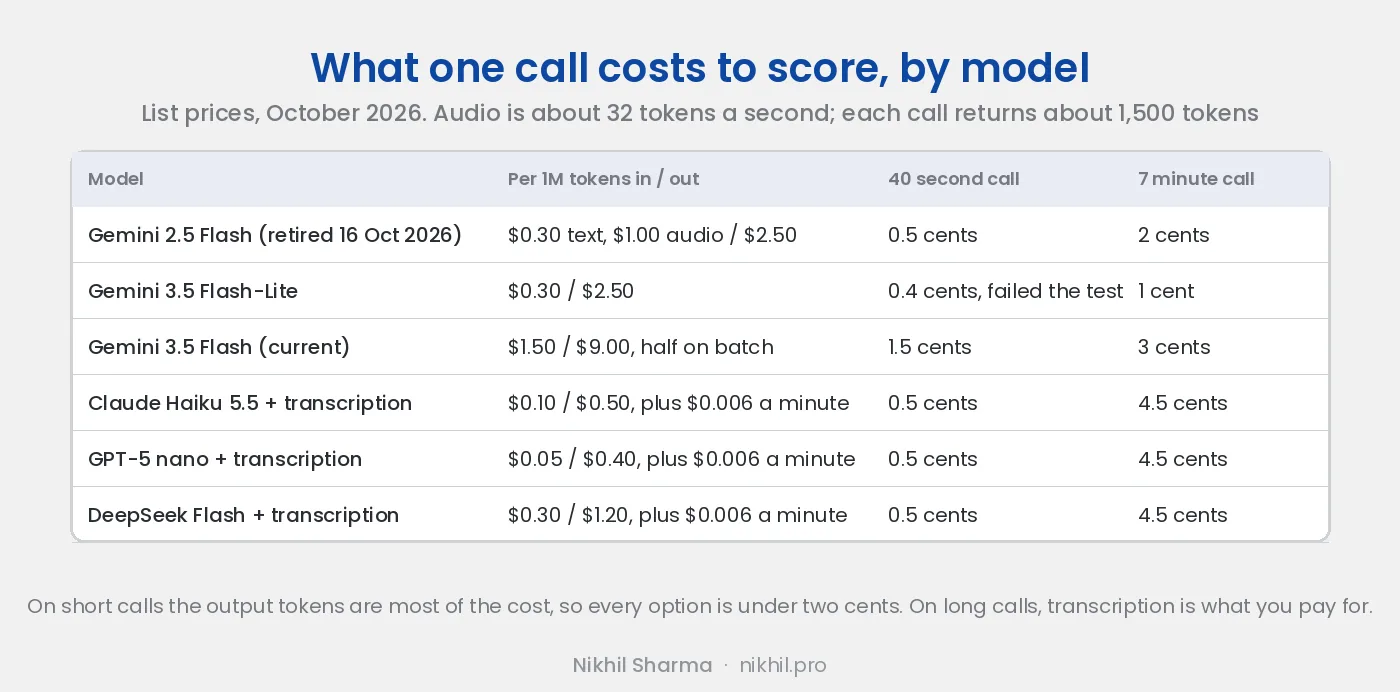
The cost was the second reason. At 2.5 Flash’s list price, $0.30 per million text tokens, $1.00 for audio, $2.50 out, a seven minute call is around 13,000 audio tokens in and 1,500 tokens out, which is about two cents. A thousand calls a month was the $15 to $25 bill above. For context, a person listening to those thousand calls at a hundred a day is a full time job.
The Flash-Lite experiment. In September I tried to move to Gemini 3.5 Flash-Lite. Same list price as 2.5 Flash, newer generation, and on paper it should have been a free upgrade. I wrote a comparison function that runs the same call through both models and prints a diff of every field.
On the first call, a six minute address problem in Spanish, the two models agreed on language, call type, outcome and issue type, and disagreed on everything that involved judgement:
- Agent performance: 8 versus 5
- Customer satisfaction: 8 versus 6
- Sentiment score: 0.4 versus 0
Across four more calls chosen for variety, Flash-Lite swapped the speaker labels on one, which would have given the agent the customer’s bad mood as a score. That is a failure a human reviewer had caught on a different call months earlier, and I was not going to reintroduce it to save nothing. Lite stayed off.
The forced move. Google retired Gemini 2.5 Flash on 16 October 2026. The replacement that passed the same diff test was 3.5 Flash, at $1.50 in and $9.00 out, five times the old price on paper. On a call it is about three cents instead of two, because audio tokens are now billed at the single input rate rather than the old audio surcharge, so the real increase was closer to half again than five times.
Batch pricing halves it if you can wait up to a day for results. I pay the on demand rate, because the point of running it on a short schedule is that the helpdesk note is there before the customer’s next call, and a day late defeats the point.
The monthly bill moved from the $15 to $25 range to around $30 to $40 for the same volume. Scores on the same calls came back within a point of 2.5 Flash, speaker labels held, and the summaries got slightly better. I took the increase.
The same job on other providers. Per million tokens, in and out:
- Claude Haiku 5.5: $0.10 and $0.50
- GPT-5 nano: $0.05 and $0.40
- DeepSeek Flash: $0.30 and $1.20
All cheaper per token than 3.5 Flash, and all text only, so each needs a speech to text model in front of it. That step costs more than the scoring model does, adds a failure point, and hands the scorer a transcript with the tone stripped out. If the task were ticket triage or tagging, text in and a label out, I would run it on Haiku or nano and pay a tenth as much. The AI customer support post covers where each tool sits.
What that means for your team, in money. Token prices are hard to picture, so here is the arithmetic in calls. Audio is about 32 tokens a second, and every call comes back with roughly 1,500 tokens of scoring whether it lasted 40 seconds or 7 minutes. On Gemini 3.5 Flash that makes a 40 second call about 1.5 cents and a 7 minute call about 3 cents. Most support calls are short, so the bill tracks how many calls you make more than how long you talk.
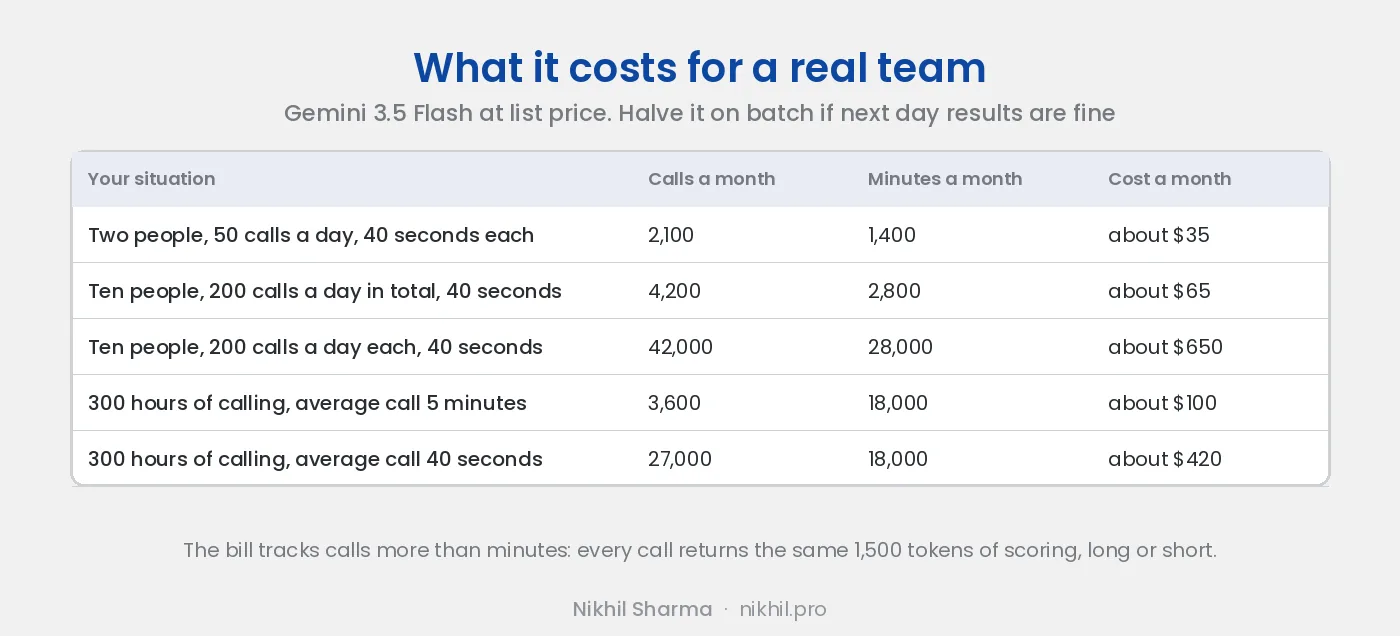
- Two people, 50 calls a day, 40 seconds each: about 2,100 calls a month, about $35.
- Ten people, 200 calls a day between them: about $65 a month.
- Ten people, 200 calls a day each (a real outbound floor): 42,000 calls, about $650.
- 300 hours of calling: about $100 at a five minute average, about $420 at forty seconds, because the short version is seven times as many calls.
Halve all of those on the Batch API if you can wait a day for the scores.
Across providers, for the 40 second call most teams actually make:
- 2.5 Flash: half a cent
- 3.5 Flash: a cent and a half
- Haiku 5.5 or GPT-5 nano with a transcription model in front: about half a cent
So for short calls the text route is cheaper by about a cent a call, which at 4,200 calls a month is $40. What you give up for the $40 is the tone the agent score is built on, plus a second vendor, a second failure point and a second bill. For long calls it flips: transcription at $0.006 a minute makes a 7 minute call about 4.5 cents on any text model, against 3 cents on Gemini.
What Broke
Three things failed in production. Worth mentioning, because every operator post that pretends nothing went wrong is lying.
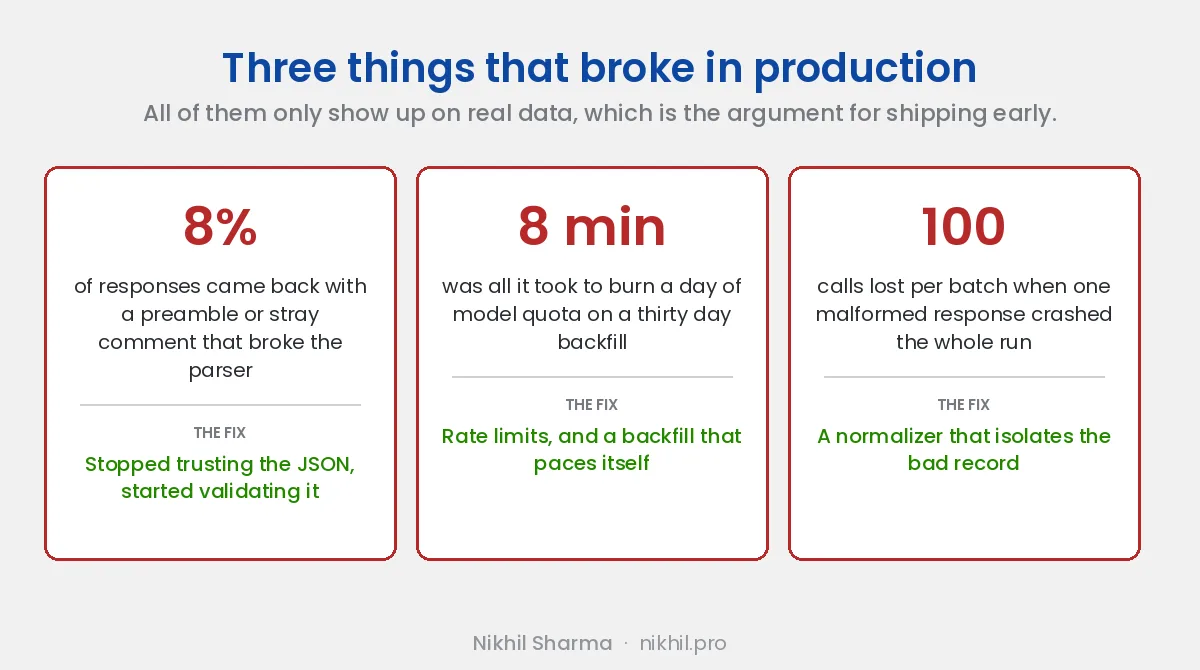
Trusting the JSON. About 8% of responses in the first week came back with a stray comment or a “Sure, here’s the analysis” preamble that broke the parser. I tightened the prompt and added a regex fallback that extracts the JSON block before giving up. Failure rate is now under half a percent.
Forgetting rate limits. The first historical backfill across thirty days of calls burned through Gemini quota in eight minutes and got blocked for an hour. The same rate limiter now sits on every entry point.
One bad response killing a batch. A single malformed response from the phone system was crashing entire batches of a hundred calls, because the script runtime doesn’t isolate errors well. A defensive normalizer now logs and skips anything weird instead of throwing.
None of these were deep bugs. They’re the kind of thing you only find on real data, which is exactly why I’m glad I shipped fast in Sheets instead of polishing a web app for a month :)
What It Cost and What Changed
Total ongoing cost: $15 to 25 a month for the Gemini API on 2.5 Flash, $30 to 40 since the move to 3.5 Flash. Zero new SaaS subscriptions. Zero hosting.
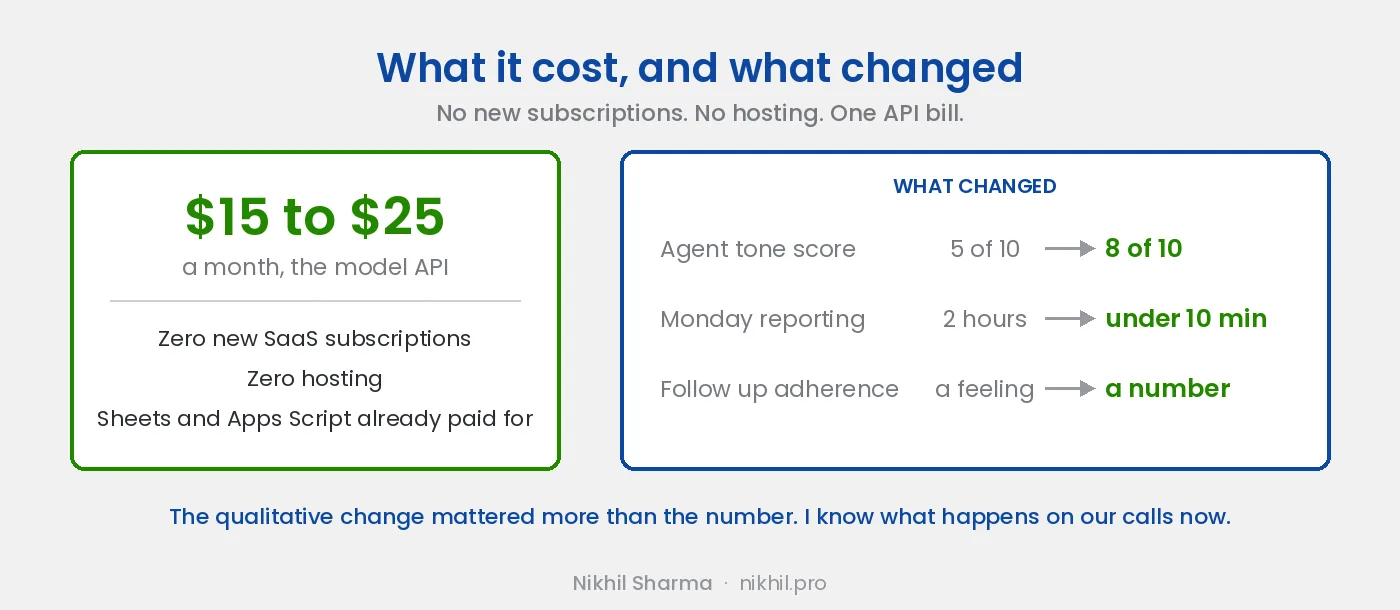
The qualitative change matters more than any number. I now actually know what’s happening on our calls.
- One agent consistently scoring 5/10 on tone got targeted coaching and is at 8 now.
- Follow-up adherence went from “I think we’re doing it” to a hard number on a dashboard.
- Monday reporting dropped from two hours to under ten minutes, because the dashboard is the report.
- Helpdesk tickets carry call summaries automatically, so the CX team starts every conversation with full context.
What I’d Tell Another Operator
Start with the workflow, not the tool. The question isn’t which model to use, it’s which decision gets made better when this recording gets analyzed automatically. If you can’t name the decision, the AI is decoration.
Spend your time on the prompt. Write it like you’re training a new hire, not querying an API. Pre-enrich your inputs with whatever context you already have sitting in Shopify or your helpdesk. Don’t make the model guess what you could just tell it.
Use the spreadsheet as long as you can. A sheet with a script behind it will outlast your assumption that you need a real app. When concurrent edits get painful, when row counts crash performance, when you truly need real-time updates, that’s when you graduate. Not before.
Don’t automate what your team should be deciding. The AI in our system surfaces, summarizes, and routes. It doesn’t auto-resolve tickets, auto-issue refunds, or auto-respond to customers. That line will move over the next year, but I’m in no rush to move it.
Eventually this pipeline will outgrow Sheets. The data model will need a real database, the dashboard will need real-time updates, we’ll add agent-facing tools with their own UI. When we get there the migration will be easy, because the Sheet will have spent its life telling me exactly what fields and what workflows actually matter.
For now, the most sophisticated piece of AI automation in the company is a Google Sheet processing call recordings through a brand-tuned Gemini prompt, and it’s working :)
If you would rather have it built than build it, this is the kind of thing I do for ecommerce teams.
Frequently asked questions
How do you analyse call recordings automatically?
Do you need a separate transcription service like Whisper?
Why build this as a script instead of a web app?
What usually breaks in an automated call analysis pipeline?
Which Gemini model is best for analysing call recordings?
What does it cost to analyse a call with Gemini?
What makes the difference in call analysis quality?
Should sentiment be scored for the customer and the agent separately?
Part of AI automation and MCP, where every guide on the subject is listed in reading order.
Get new posts in your inbox
Occasional notes on Shopify, paid ads, and what I learn. No spam.
Thanks. Check your inbox to confirm.
Nikhil Sharma
Nikhil Sharma runs data and operations for a DTC brand on Shopify and consults for Shopify brands on Meta and Google ads, conversion and AI automation. He writes case studies and implementation guides from accounts and systems he has run himself.