
Why Meta Only Spends on a Few of Your Ads (Creative Similarity Explained)
You launched 30 ads. Meta spent on 4. That is not a budget bug, a learning phase problem, or bad luck. Meta’s retrieval system grouped most of them into a single entity and gave that group one entry into the auction. Here is how to check whether it is happening to you, and what actually creates a genuinely distinct ad.
Almost every account I look at has some version of this problem. A batch goes live, budget concentrates on two or three ads, and everything else sits at near-zero spend. The usual diagnosis is that the winners are just better.
Sometimes that is true. Increasingly it is not.
What Actually Happens When You Upload 30 Similar Ads
Meta rebuilt its ad retrieval system, and the part that matters here is how it decides which of your ads even enter the auction.
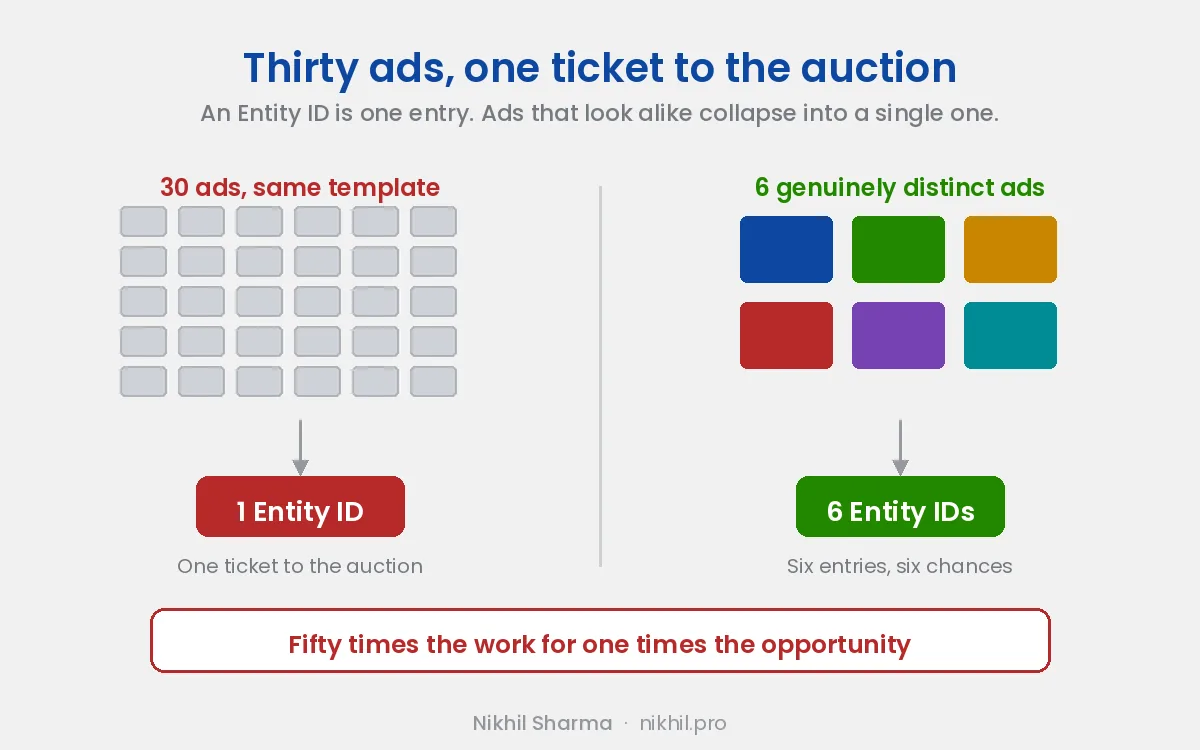
Andromeda scores every ad with computer vision on the visuals, language processing on the copy, and audio analysis on video. Ads that score above a similarity threshold across those dimensions are collapsed into one Entity ID, and an Entity ID is one ticket to the retrieval auction.
Upload 30 ads on the same template, same background and same structure with different text overlays, and you get one ticket. If it fails for a user segment, the other 29 never get a chance; they do not exist in that auction. You are not flooding the system with options. You are doing 30x the work for 1x the opportunity.
The uncomfortable implication: a lot of what teams call creative testing is not testing anything. Four hooks over the same B-roll is one ad wearing four hats.
Is Concentrated Spend Good or Bad?
The question every large account asks once it notices that two or three ads take most of the budget. The answer is that concentration on its own tells you nothing. It is the system doing its job, or it is a production problem showing up as a performance result, and the two look identical in the spend column.
Think of it as two stages. Andromeda is the retrieval layer: it looks at everything in the account and picks a shortlist of candidates for each person. Lattice is the ranking layer: it decides which of those candidates wins the auction. The catch is in the first stage. Andromeda groups ads that look alike into one entry, and that entry gets one ticket into the shortlist. So if 30 ads are really 3 ideas in 10 outfits each, Andromeda sees 3, Lattice ranks 3, and spend lands on 2 or 3. That looks like concentration, but you tested 3 ideas and paid for 30.
The way to tell which you have: list every ad that spent in the last 30 days, group them by concept using the first frame test further down, and count. If the spend is concentrated on three ads and you had three concepts, the system chose. If it is concentrated on three ads and you had twelve concepts, that is a real result and the other nine lost. If you had three concepts dressed as thirty ads, you have not run a test yet. At six figures a month the difference between those three readings is most of the creative budget.
Where to Check It in Ads Manager
This used to be pure inference. Meta now gives you a partial view.
You get three metrics there:
| Metric | What it tells you |
|---|---|
| Creative Similarity Score | How alike your ads look to Meta’s system. A proxy for Entity ID overlap |
| Creative Fatigue Score | Whether an audience has seen a creative too many times |
| Top Creative Themes | Which thematic buckets your ads fall into, and how budget splits across them |
Top Creative Themes is the fastest read of the three. It sorts your ads into buckets like lifestyle, product-focused, testimonial, humor, social proof, and savings. If most of your budget sits in one bucket, you are clustered on a single branch of the tree and the similarity number is only confirming it.
The thresholds
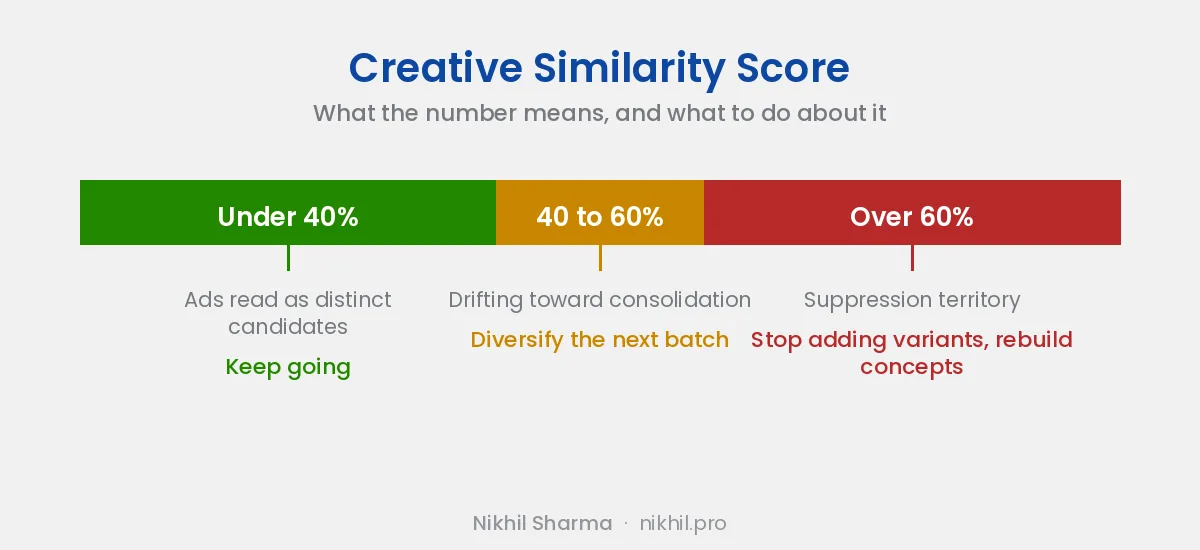
When the Creative Similarity Score passes 60%, the system collapses the ads into one Entity ID. 303 London’s diversity guide recommends keeping it below 40% across active assets so each ad is treated as a distinct candidate.
Why Copy Changes Do Not Save You
The most common mistake is assuming that different words mean different ads.
Computer vision looks past the headline and the hook to the composition and style of the content. Overlap there means one Entity ID, whatever the script says. So the following almost certainly do not produce new entities:
- New headline over the same hero image
- New primary text on the same video
- Same template, different colour
- Same footage, different caption style
- Same talent, same setting, same framing, different script
The diversity needs to register at the visual, audio, and structural level the model is actually parsing.
What Actually Creates a Distinct Ad
Andromeda organises ads into a tree: top level themes (social proof, product focused, lifestyle, humour), mid level execution patterns (direct to camera, split screen, animation, UGC), and individual creatives at the leaves. A diverse pool is one whose ads land across different branches, not clustered on one.
That gives you a practical way to plan a batch. Vary along these axes, not along copy:
| Axis | Weak variation | Real variation |
|---|---|---|
| Footage | Same clips recut | New shoot, new location, new talent |
| Format | Same video, new caption | Talking head vs montage vs static vs carousel |
| Opening 2 seconds | New text overlay | Different subject, framing, and motion entirely |
| Audio | Same VO, new music | Different voice, different pacing, or silence |
| Structure | Reordered beats | Different narrative shape altogether |
| Theme | Same claim, new words | Different reason to buy |
How Many Ads, Really
Volume is part of this now, but only distinct volume.
Brands testing 20+ new ads per month are seeing 65% higher ROAS than brands testing under 10. The top-performing advertisers run roughly 395 live ads versus 296 for the bottom third.
The caveat is the whole point: 395 ads that all look the same perform no better than 10, because they are one entity.
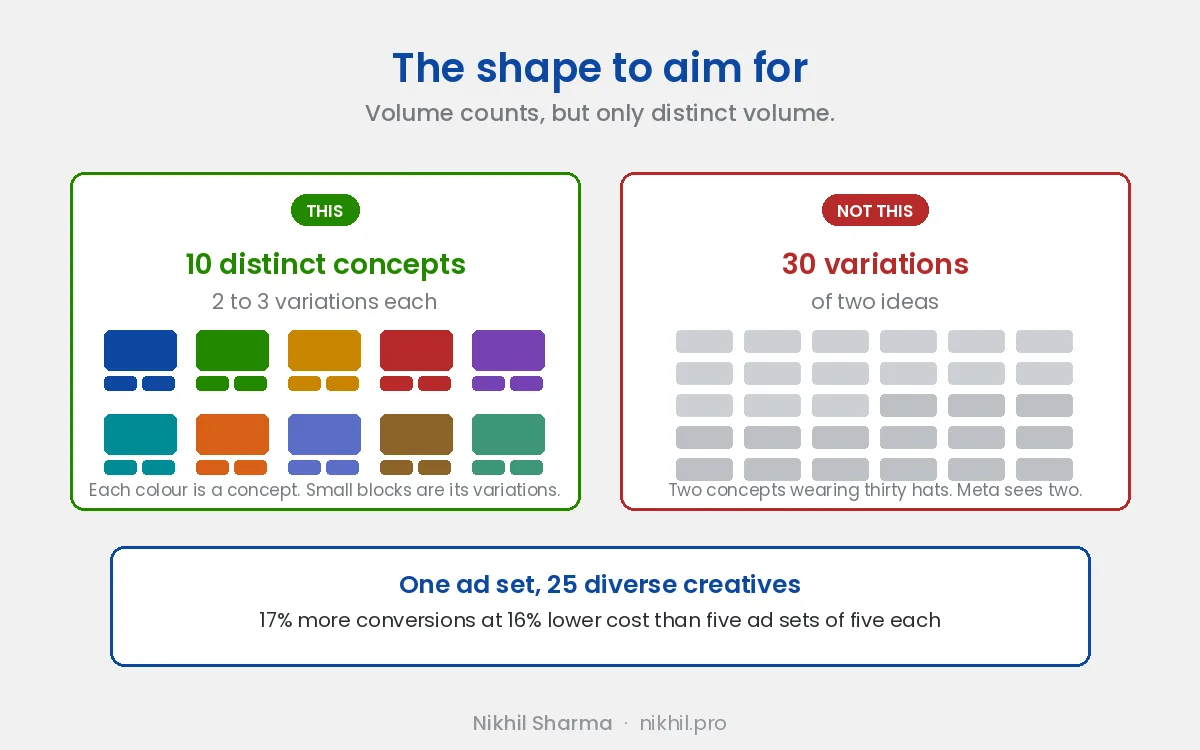
One structural finding to go with it: one ad set with 25 diverse creatives generated 17% more conversions at 16% lower cost than five ad sets of five. Consolidating gives the system a wider pool to retrieve from.
Making Ten Concepts Without Ten Shoots
The obvious objection is cost. Ten distinct concepts with two or three variations each is thirty assets, and nobody is booking thirty shoots a quarter. This is where generative video earns its place, and where most people immediately misuse it.
I use Higgsfield for this, generating stills with Seedream and animating them with Seedance. The full workflow is in the AI UGC guide, but the short version is that you write the scene, generate stills, pick the one that looks right, and animate that still with a motion prompt. Prompting video from scratch gives you no control over what the scene actually looks like.
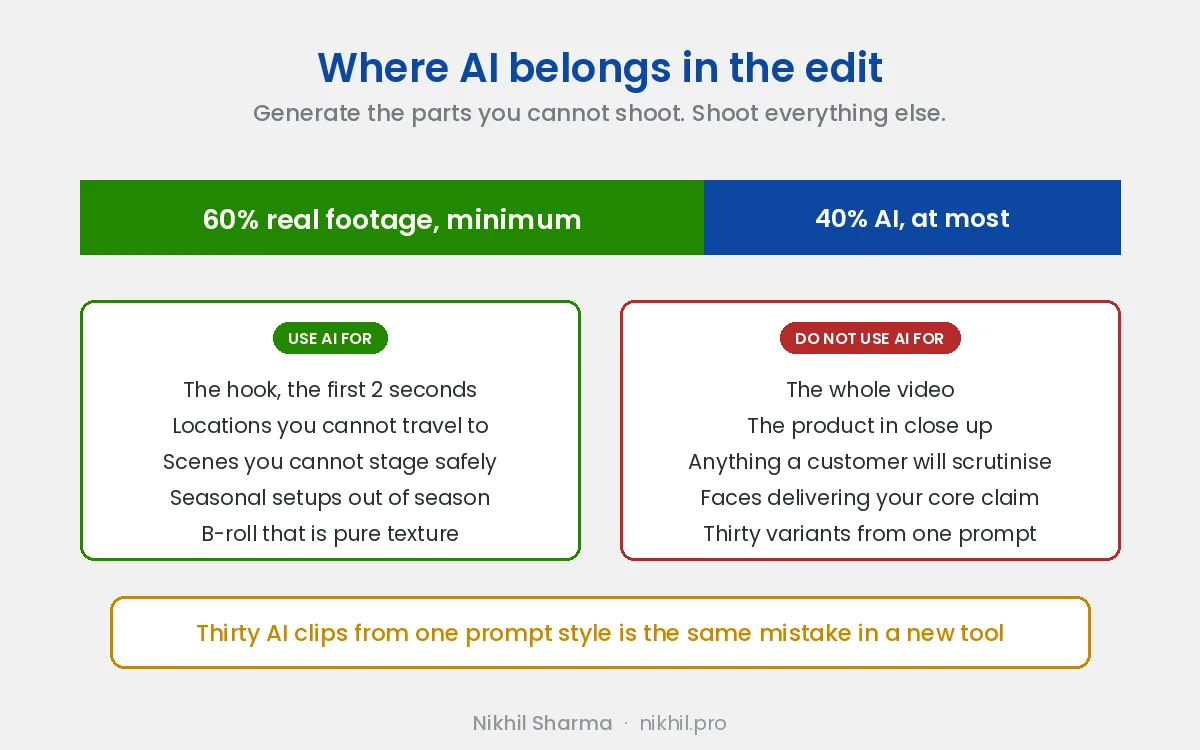
Do not generate the whole video. Keep at least 60% of every ad as real footage. Use AI for the opening two seconds, for a location you cannot get to, for a seasonal setup you cannot shoot in the current season, and for texture B-roll nobody will study. Shoot the product, shoot the faces making your actual claim, and shoot anything a customer will look at closely.
Thirty clips from one model with one prompt style reproduce the exact problem: visually consistent output the retrieval system reads as one thing. The tool changed, the mistake did not. AI video expands how many different scenes you can afford; it does not excuse you from making them different.
Used that way, ideas are the cheap part. Mock up eight openings in an afternoon, see which look distinct in a grid, and shoot around the ones that survive.
Refresh Cadence, Because Fatigue Got Worse
The second order effect nobody warns you about: fatigue got worse. Relaunching a campaign or swapping hooks used to reset performance; Andromeda degrades repeated messaging fast, and the duplicate and relaunch trick does not work the way it did.
The cadence most practitioners are landing on is 50/30/20 on a two to three week cycle: 50% new concepts, 30% refined variants, 20% proven performers.
A Diagnostic You Can Run This Week
Six steps, in order.
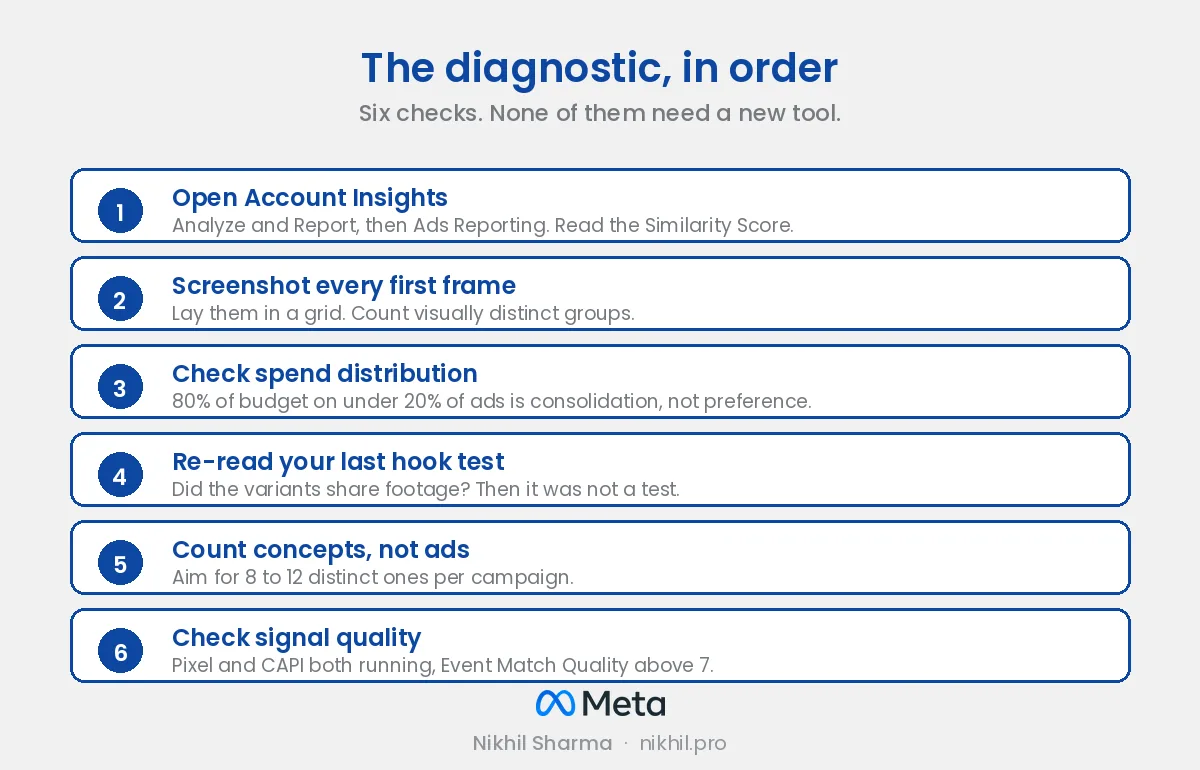
- Open Analyze & Report → Ads Reporting → Account Insights. Check the Creative Similarity Score and the Top Creative Themes split. Anything over 60% similarity, or most of your budget in one theme, is your answer.
- Screenshot the first frame of every live ad and lay them out in a grid. Count how many visually distinct groups you actually have. That number, not your ad count, is roughly what Meta sees.
- Check spend distribution. If 80% of budget sits on under 20% of ads and the rest are near zero, that is consolidation, not a preference.
- Look at your last “hook test.” Did the variants share footage? If yes, it was not a test.
- Count real concepts, not ads. Aim for 8 to 12 distinct ones per campaign.
- Check signal quality while you are in there. Clean conversion signal quality (Pixel and CAPI running simultaneously, Event Match Quality above 7) is the other half of this, because the retrieval system is only as good as the events you feed it.
If you would rather have this run for you
Meta and Google Ads for Shopify brands
Similarity score, concept count and spend distribution checked on your account first, then the structure and the creative system to fix them. US, Canada and Europe.
Not sure yet
Account read on a call
Thirty minutes with Ads Manager open. You leave with the six checks above done and a list of what to change first.
What This Changes About Testing
The old model was narrow targeting plus a high volume of similar creatives. The Andromeda model is broad targeting plus a high diversity of Entity IDs. Two consequences:
Creative is the targeting layer now. Interest settings are unavailable or far less influential, so ads reach the people who respond to the message rather than a demographic box. You choose your audience by what you make, not by what you tick.
Your test design has to change. If you want to know whether a question hook beats a bold-claim hook, the two versions cannot share footage, or you will get one entity and a meaningless read. Test the variable, but rebuild everything around it enough that the system treats them as separate.
I wrote more about the mechanics of the ranking change in my post on Meta’s Andromeda system, and the practical scaling side in the 2026 Shopify Meta Ads scaling guide. If your creative is fatiguing faster than you can replace it, fixing ad fatigue covers that separately.
There Is No Fixed Framework, Only Rules
People ask for a creative testing framework that works under Andromeda. The honest answer is that there is not a fixed one and there will not be, because the system changes faster than a framework can be written down. What holds up is a short set of rules that survive the changes:
- What counts as a new idea. Different footage or image, different opening two seconds, different setting or person, or a different format. Not a new caption, colour or crop on the same asset. Write this definition down and make the creative team apply it before anything is uploaded.
- How many run at once. Enough distinct concepts for the shortlist to have a choice, 8 to 12 in an account of any size, and no more variants per concept than you can tell apart at a glance.
- When to kill. An ad that has spent nothing after a week was never in the shortlist; kill it, do not pause and relaunch it, because relaunching the same asset recreates the same entry. An ad that spent and lost is a result; record it as a concept that lost and move on.
- What to do with winners. Make the next batch of concepts from what the winner is about, not from the winner’s footage. New ideas in the same direction, not the same idea in new outfits.
Everything else, the number of ad sets, CBO against ABO, the budget per test, is detail that changes with the account and the quarter. These four do not.
The Short Version
Meta is not ignoring your ads. It grouped them.
Similar creative collapses into one Entity ID, one Entity ID gets one entry into the retrieval auction, and everything underneath it competes for the same slot instead of expanding your reach. Copy changes do not break the grouping. Visual, audio and structural difference does.
Check your Creative Similarity Score, keep it under 40%, build 8 to 12 genuinely distinct concepts rather than 30 variants of two, and refresh on a two to three week cycle.
And stop calling it a hook test if all four versions share the same footage.
I’m Nikhil Sharma. I run data and operations engineering for a DTC brand and write about the unglamorous parts of ecommerce that actually move margin. If you want a second pair of eyes on your ad account or creative pipeline, book a consultation.
Frequently asked questions
Is concentrated spend on a few Meta ads good or bad?
Why is the Creative Similarity Score missing from my Account Insights?
Is there a creative testing framework that works under Andromeda?
What is an entity ID in Meta ads?
Why is Meta only spending on one or two of my ads?
What is Creative Similarity Score?
Where do I find Creative Similarity Score in Ads Manager?
What is an Entity ID in Meta ads?
Does changing the copy or headline create a new Entity ID?
How many ads should I run under Andromeda?
Is hook testing still a valid test on Meta?
How often should I refresh creative under Andromeda?
Is interest targeting dead under Andromeda?
Part of Meta, Google and ChatGPT ads, where every guide on the subject is listed in reading order.
Get new posts in your inbox
Occasional notes on Shopify, paid ads, and what I learn. No spam.
Thanks. Check your inbox to confirm.
Nikhil Sharma
Nikhil Sharma runs data and operations for a DTC brand on Shopify and consults for Shopify brands on Meta and Google ads, conversion and AI automation. He writes case studies and implementation guides from accounts and systems he has run himself.